Reducing Pod Startup Times - Part 1: Running an Image Pool
A pod can sit in ContainerCreating for minutes on a node that has been up for weeks. It has capacity. It just doesn't have the image. Part 1: keeping an image pool warm on every node, and where that breaks.
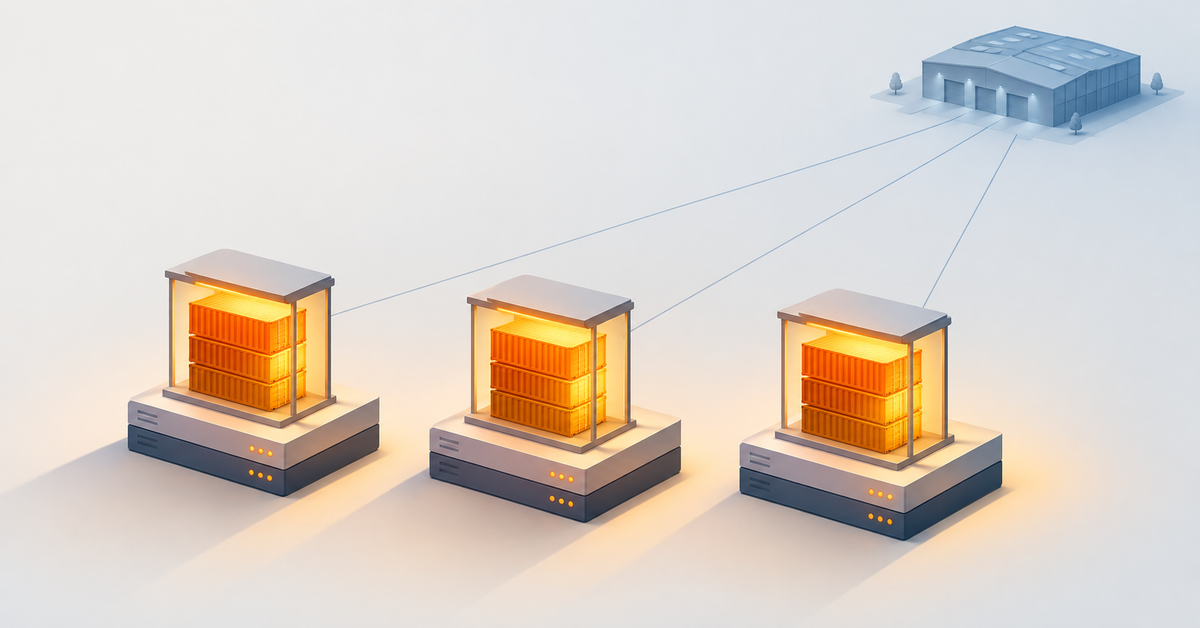
Every Pod's startup consists of multiple phases like scheduling, image pulling, sandbox creation, unpacking the layers into a snapshort, wiring up the CNI, starting the Container and waiting for Probes to pass. From this list the Pull is by far the most variable step and the one that scales with the size of your Images rather than with anything you control at runtime.
A long Pull Time is bad and it hurts especially in scenarios like the following:
- Batch and CI workloads with short runtimes, where the pull takes longer than the actual job
- CronJobs that land on a different node every time they run
- ML and AI images in the tens of gigabytes
- Rescheduling after a drain, an eviction, or a node failure
- Nodes running many different workloads, where image garbage collection keeps cleaning up
- Live demos and workshops, where you only have limited time
What if we could eliminate this Pull Time completely?
What This Solves and What It Doesn't
Before jumping into the solution, it is worth being precise about the scope up front, because there are some limitations to that approach. Running an Image Pool helps with Pod starting on existing Nodes. If the node already has the Image on disk the Pull disappears entirely and the Pod starts in seconds.
However, it does not help with freshly provisioned nodes. When Cluster Autoscaler or Karpenter adds a node, the Image Pool Component has to pull the image just like everyone else. It sits in the same queue as the workload that triggered the scale-out and competes with it for the same bandwidth. In the worst case, the Pool can make a cold start slower.
That split is exactly why this is a two-part series. Part 1 is about keeping a list of Images on your existing Nodes. Part 2 is about the cold start, and that is where Spegel comes in.
Why Image Pulls Are Slow
When looking at why Image Pulls are slow, we can identify three things that dominate.
- The network and the registry:
Latency, available bandwidth, rate limits of the registry and egress costs. With n nodes, the same image travels over the same link n times, and every one of those pulls is billed and rate-limited independently. - Decompression, not download:
For large layers the bottleneck is frequently unpacking rather than transfer. Gzip decompression is single-threaded per layer, so a fat base layer does not get faster on a bigger machine. - Serialization inside the kubelet:
By default theserializeImagePullssetting of the kubelet is set totrue, which results in images being pulled one at a time . You can set it tofalseand then bound the concurrency withmaxParallelImagePulls. Keep this in mind, because it comes back later in a way that is not obvious.
If you want to learn how to run your own Harbor instance to work around the rate limitation of your target registry, I have something you might be interested in.
The Core Idea: Images In Use Are Never Garbage Collected
The kubelet reclaims disk by deleting images once imageGCHighThresholdPercent (85% by default) is reached. But it never deletes an image that is currently in use.
That single rule is the whole trick:
If every node runs a pod that references an image, that image stays on the node.
A DaemonSet gives you exactly that: one pod per node, including on nodes that join later. The pod does not need to actually do anything. It only needs to exist and hold a reference to your Image.
For this to pay off, your workloads need imagePullPolicy: IfNotPresent, which is the default for anything not tagged :latest. With Always, the kubelet still contacts the registry on every container start. You save the layer downloads, but not the round trip.
The Classic Approach: A DaemonSet With Init Containers
Jacob Tomlinson described the standard version of this in Quick and dirty way to pre-pull container images on Kubernetes (2023). One init container per image, each running a no-op so it terminates immediately, followed by a pause container that keeps the pod alive:
initContainers:
  - name: prepuller-1
    image: ORG/IMAGE:TAG
    command: ["sh", "-c", "'true'"]
containers:
  - name: pause
    image: registry.k8s.io/pause:3.10
It works, and for a handful of images it works fine. Three things get uncomfortable as the list grows.
- You need a command that actually exists in the image:
scratchand distroless images have no shell, sosh -c 'true'fails. You end up needing to know what is inside each image before you can cache it, which does not scale when the point is to maintain a generic list. - Every image has to be started, not just pulled:
Create a container, start it, wait for it to exit, move to the next one. - Containers cost resources: Each container has requests, limits and an effect on the pod's QoS class. A pod's effective resource request is at least the maximum across all of its init containers, and omitting requests entirely pushes the pod into
BestEffort. - There is also a Security angle:
Starting third-party images as init containers can run into Pod Security Standards such asrunAsNonRoot.
A Cleaner Approach: Image Volumes
KEP-4639 added the ability to mount an OCI image directly as a read-only volume, without ever running it as a container:
containers:
  - name: pause
    image: registry.k8s.io/pause:3.10
    volumeMounts:
      - name: my-app
        mountPath: /images/my-app
volumes:
  - name: my-app
    image:
      reference: registry.example.com/org/my-app:1.4.2
      pullPolicy: IfNotPresent
This solves all of the four problems of the classic approach. The Image is not started, you don't need to define any commands or resources and your Pod Security Standards don't care about a Volume.
This approach is safe as the kubelet's image GC manager specifically accounts for images used as mounts and treats them as in use. And the kubelet also exposes image volume metrics since 1.33.
Running It: The node-image-cache Helm Chart
I have packaged the image volume approach as a Helm chart, that you can use to easily install your own Image Pool:
helm repo add christianhuth https://charts.christianhuth.de
helm repo update
helm install node-image-cache christianhuth/node-image-cache -f values.yaml
For a complete list of configuration value, see the corresponding Artifact Hub page. But there are some settings you should think about, when using the Chart:
- Tolerations. Without them the cache pod will not land on tainted nodes, which usually means it skips exactly the GPU nodes holding your largest images.
- PriorityClass. The cache pod should have low priority so it never preempts real workloads. At the same time you want it scheduled early during node bootstrap.
- Multiple releases. The chart is designed to be installed more than once. Split it per node pool, so GPU images do not end up on CPU nodes, or per image group.
Here is a realistic example for a GPU node pool:
# values-gpu.yaml
images:
  - name: cuda-runtime
    image: nvidia/cuda:13.1.2-cudnn-runtime-ubuntu24.04
  - name: vllm
    image: vllm/vllm-openai:v0.28.0
  - name: triton
    image: nvcr.io/nvidia/tritonserver:25.10-py3

# Only place this release on nodes that actually have an NVIDIA GPU.
# nvidia.com/gpu.present is applied by GPU Feature Discovery, which ships
# as part of the NVIDIA GPU Operator.
nodeSelector:
  nvidia.com/gpu.present: "true"

# GPU nodes are almost always tainted so that ordinary workloads stay off
# them. Without this toleration the cache never lands where it matters most.
tolerations:
  - key: nvidia.com/gpu
    operator: Exists
    effect: NoSchedule

priorityClassName: node-image-cache-low

resources:
  requests:
    cpu: 10m
    memory: 16Mi
  limits:
    memory: 32Mi
Now do the arithmetic on that example, because it is a good illustration of the limits discussed below. The CUDA cuDNN runtime image is a few gigabytes, vllm/vllm-openai is around 10 GB, and NGC's Triton and PyTorch images run into the tens. This one release can easily pin 30 GB or more on every GPU node, permanently, with the image GC unable to touch any of it. That is usually fine on GPU nodes, which tend to have large disks, but it is a number you want to have checked against imageGCHighThresholdPercent before rolling it out rather than after.
It is also a good illustration of the serialization point from earlier: those 30 GB get pulled one image after another by a single pod. Splitting inference images and training images into two releases is worth doing for warm-up time alone.
Note that every image above is pinned to a specific version. Given the tag drift discussion below, that is the minimum. Digests would be better.
Limitations and Failure Modes
The Cache Is Cold Exactly When You Need It
A new node does not have the pool yet. The DaemonSet has to pull first, competing for bandwidth with the workload that caused the scale-out in the first place. The same applies when you roll out a new image version. The pool is cold until the DaemonSet has been updated and has finished pulling everywhere.
The approach helps with repeated starts on existing nodes. For genuine cold starts you need something else.
Operational Risks
- Disk usage. Number of images times their size, on every node. With ML images that reaches three digits in gigabytes quickly.
- Garbage collection can no longer free anything. This is the most important warning in this post. Images in use are off-limits to the image GC. If the pool grows too large,
imagefsfills up, the GC has nothing it is allowed to delete, the node goes intoDiskPressure, and it starts evicting pods. Size the pool againstimageGCHighThresholdPercentand the actual disk, and monitorimagefsutilisation. - Registry load during rollout. Every node pulls at the same time. Docker Hub rate limits, egress costs, and load on your own registry all apply.
- One extra pod per node. It occupies a pod slot, which counts against
maxPods, plus requests and a watch on the API server. On small nodes the pod slot matters more than the resources.
Tag Drift: When the Cache Pins the Wrong Image
The underlying issue: a tag is a pointer, not content. The pool remembers what the pointer resolved to at pull time. If the pointer moves afterwards, the node has no idea, and because the cache keeps that image permanently in use, the GC will never clean it up. The problem does not heal on its own.
Therefore this approach only works cleanly with immutable references, whether that means tags your conventions never overwrite or digests such as api@sha256:bbb….
Which Pull Policy Belongs on an Image Volume?
The question only arises with mutable tags. If the reference is immutable, re-checking the registry cannot produce a different answer than the first pull did. One pull is enough and IfNotPresent is the only sensible choice.
Always brings a second problem that is easy to miss, as the kubelet always attempts to pull with that setting. But what happens, when the registry is down? The cache pod does not start and the image is not available, resulting in a non-functioning cache, when you would need it the most.
For mutable tags Always would at least be effective. The pool re-resolves, the local tag afterwards points to the new digest, and the workload gets the right version through IfNotPresent. But the price is steep: one registry round trip per image, per node, per sync interval (at 200 nodes and 20 images that becomes a rate limit problem), plus a race over whether the pool re-resolves before the workload starts.
| Reference | Pull policy | Reasoning |
|---|---|---|
Digest (@sha256:…) | IfNotPresent | Content cannot change, one pull is enough |
| Immutable tag (by convention or enforced by the registry) | IfNotPresent | Same |
Mutable tag (:latest, :main, floating :1.4) | – | Always treats a problem you are better off not having |
In short, Always is not a fix for tag drift. It is a symptom of mutable tags being in play.
One trap worth knowing: the pull policy on an image volume follows the same defaulting rule as container images, meaning Always for :latest and IfNotPresent otherwise. Put an nginx:latest in your image list and that one volume silently gets Always, including the "cache pod will not start without the registry" behaviour above.
Conceptual Limits
- A second source of truth. The image list has to be kept in sync with the actual workloads by hand. Drift is the normal state, not the exception.
- Security and multi-tenancy. A pre-pulled image is usable on that node by any pod with
IfNotPresent, regardless of whether that pod's owner has access to the registry. Kubernetes addresses this withKubeletEnsureSecretPulledImagesand theimagePullCredentialsVerificationPolicyfield, enabled by default since 1.35. - It treats the symptom. A 12 GB image is still a 12 GB image. Slimming it down addresses the cause.
- No sharing between nodes. Every node pulls for itself, straight from the registry. This is the one Part 2 is about.
- Observability is thin. The clearest signal that the cache is working is the
Container image "…" already present on machineevent.
Conclusion
An image pool on a DaemonSet is simple, easy to reason about, and works immediately for a stable, manageable set of images on existing nodes. Using image volumes makes the implementation considerably cleaner than init containers: no commands, and no assumptions about what is inside the images you are caching.
Its two hard limits are that new nodes are cold, and that every node pulls for itself.
That second one is where Spegel comes in. Rather than serving each node individually from the registry, it turns the cluster itself into the registry. That is Part 2.
Alternative Approaches
Pre-pulling is one answer among several, and depending on where your pull time actually goes, it may not be the one with the best return. Here is an (probably incomplete) list of alternative approaches:
| Approach | Examples | Good for |
|---|---|---|
| P2P distribution inside the cluster | Spegel, Dragonfly, Kraken | Nodes pull from each other instead of the registry → Part 2 |
| Pull-through cache / mirror | Harbor proxy cache, Zot, registry:2, Artifactory with containerd hosts.toml | Registry load, rate limits, egress |
| Baking images into the node image | Custom AMI or VM image, ctr images import at boot, GKE secondary boot disks, EKS AMI caching | The cold start problem, since the node is warm from second zero |
| Declarative pre-pull operator | kube-fledged with its ImageCache CRD | Same as the DaemonSet approach, but with refresh and status reporting |
| Lazy pulling / streaming | eStargz with stargz-snapshotter, Nydus, SOCI | Starting the container before the image is fully present |
| kubelet tuning | serializeImagePulls, maxParallelImagePulls, registryPullQPS/registryBurst | The cheapest lever, and frequently overlooked |
| Slimmer images | Multi-stage builds, distroless, layer ordering, zstd layers | Fixing the cause instead of the symptom |
| Warm node pools | Overprovisioning with pause pods, Karpenter | Node bootstrap and image pull at the same time |
| Moving data out of the image | Models and assets via image volumes or a PVC | When the size comes from data rather than code |


